【解决方案】修改PPT中指定文本框中的文本(包括加粗、标红) 收藏
评论
收藏【解决方案】修改PPT中指定文本框中的文本(包括加粗、标红)
小
2024-10-19 14:12·浏览量:706
小
小曼
背景:
客户有一个PPT模板如图:
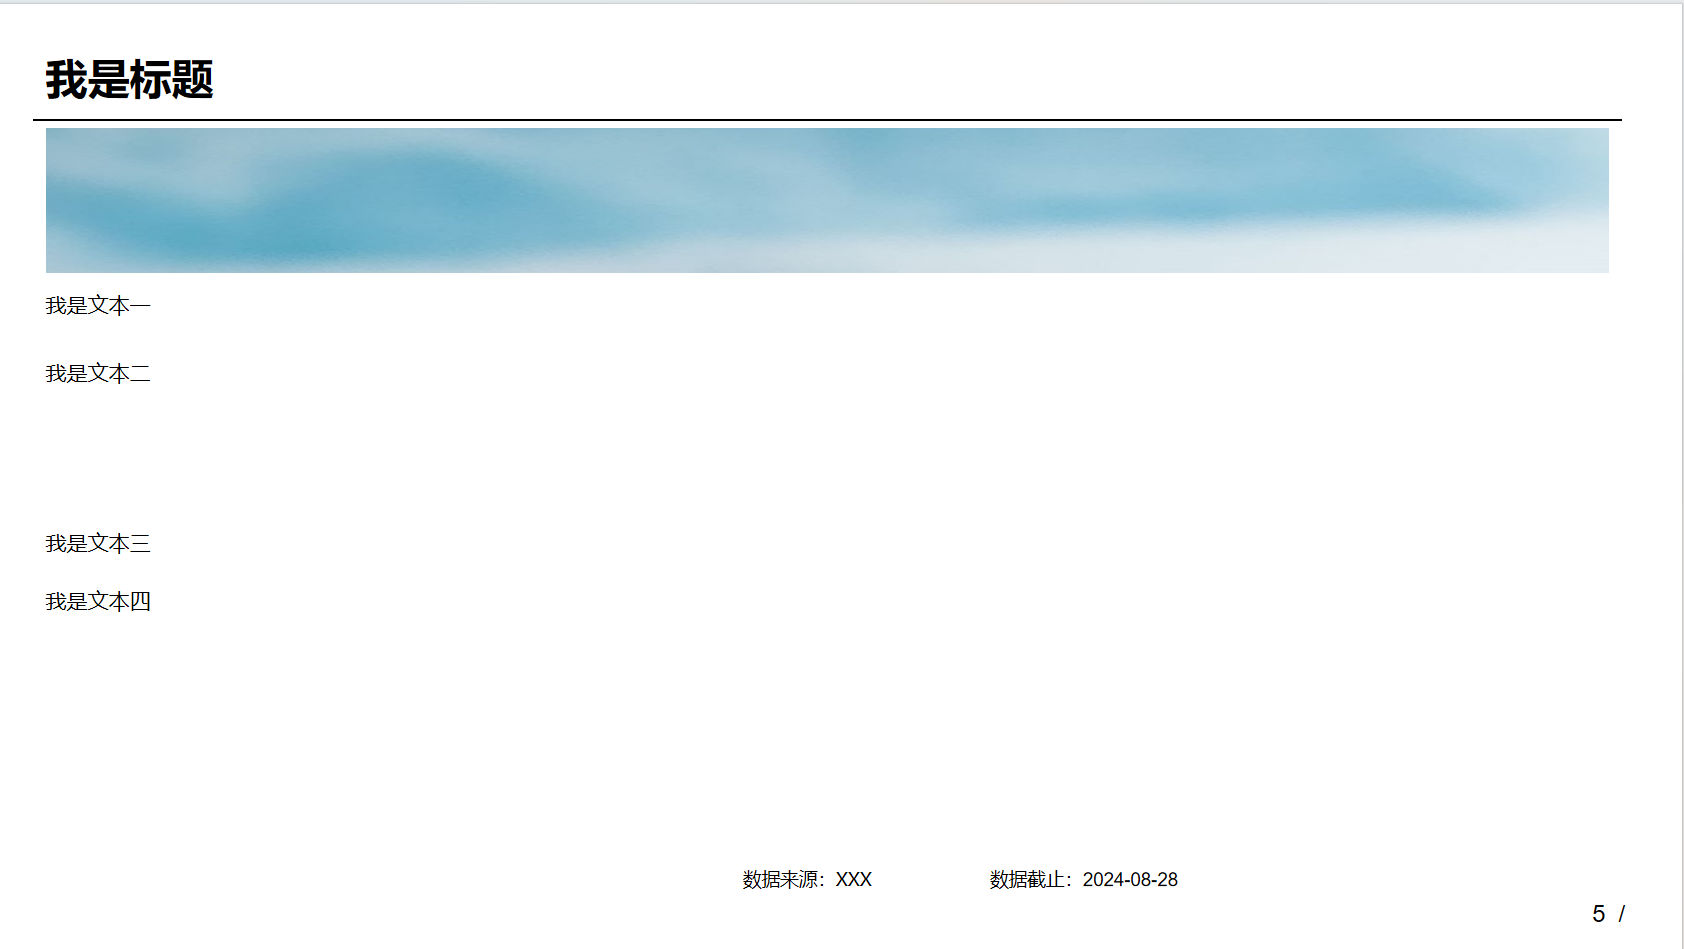
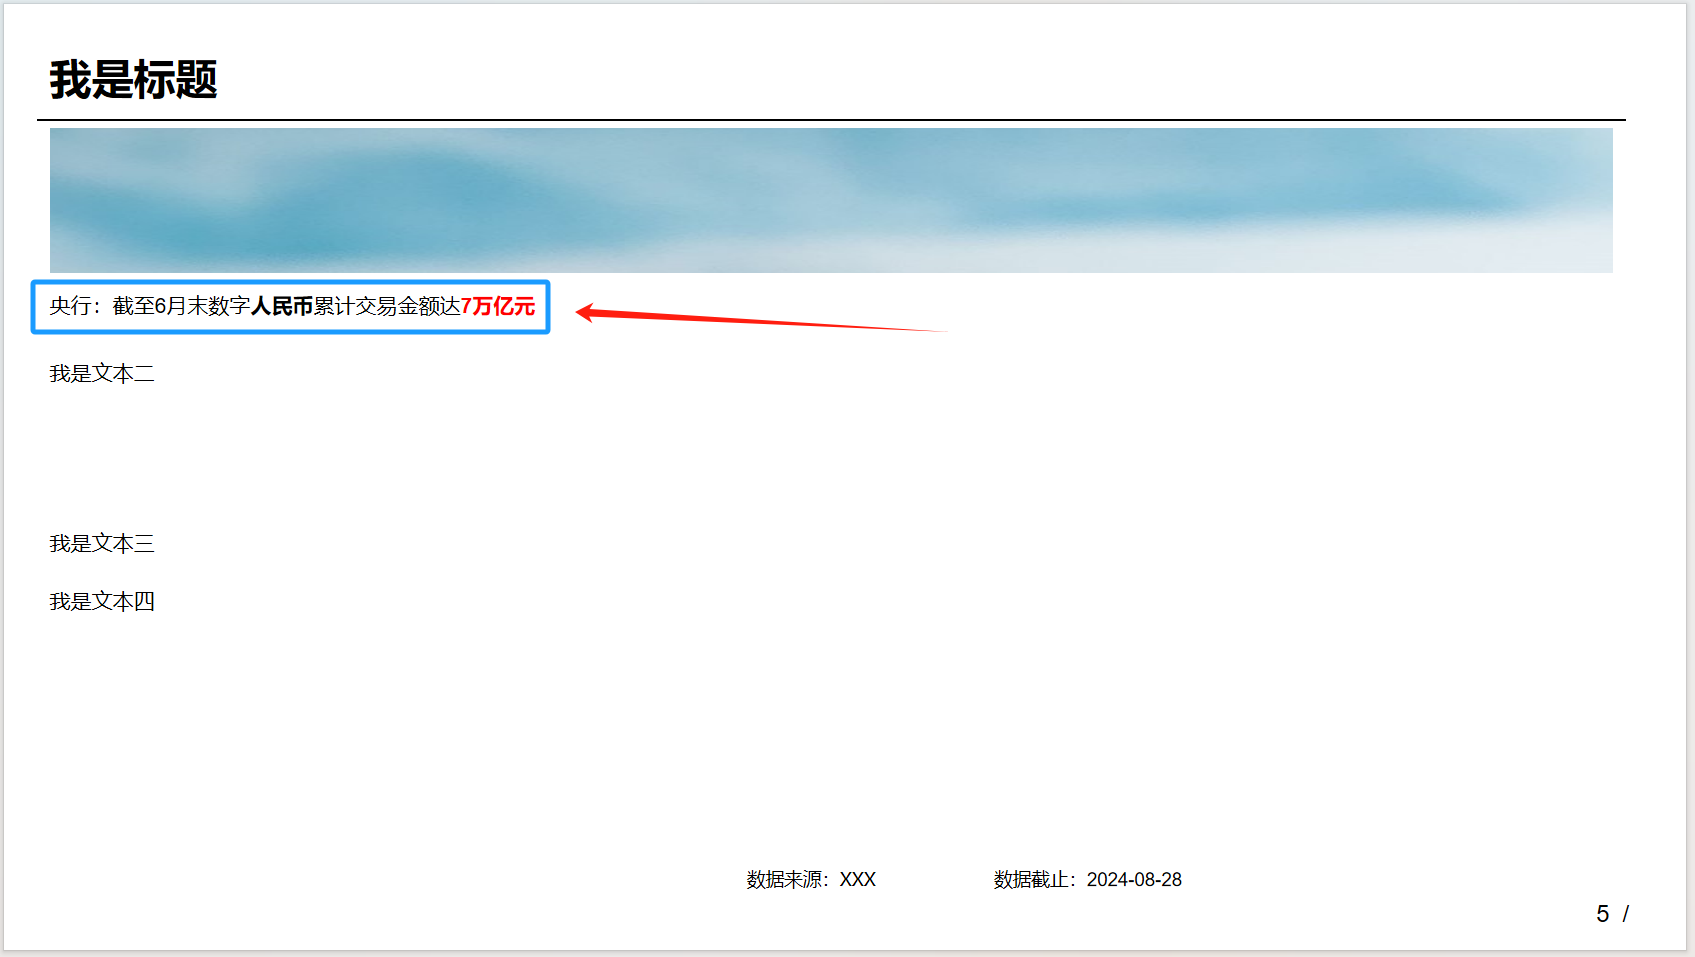
想要修改PPT中的文本,例如将“我是文本一”换成“央行:截至6月末数字人民币累计交易金额达7万亿元”,而且需要对部分字体进行标红或者加粗。
例如:将文本“人民币”加粗不标红,“7万亿元”标红并加粗。其他词语保持原样式不变。
如图所示:
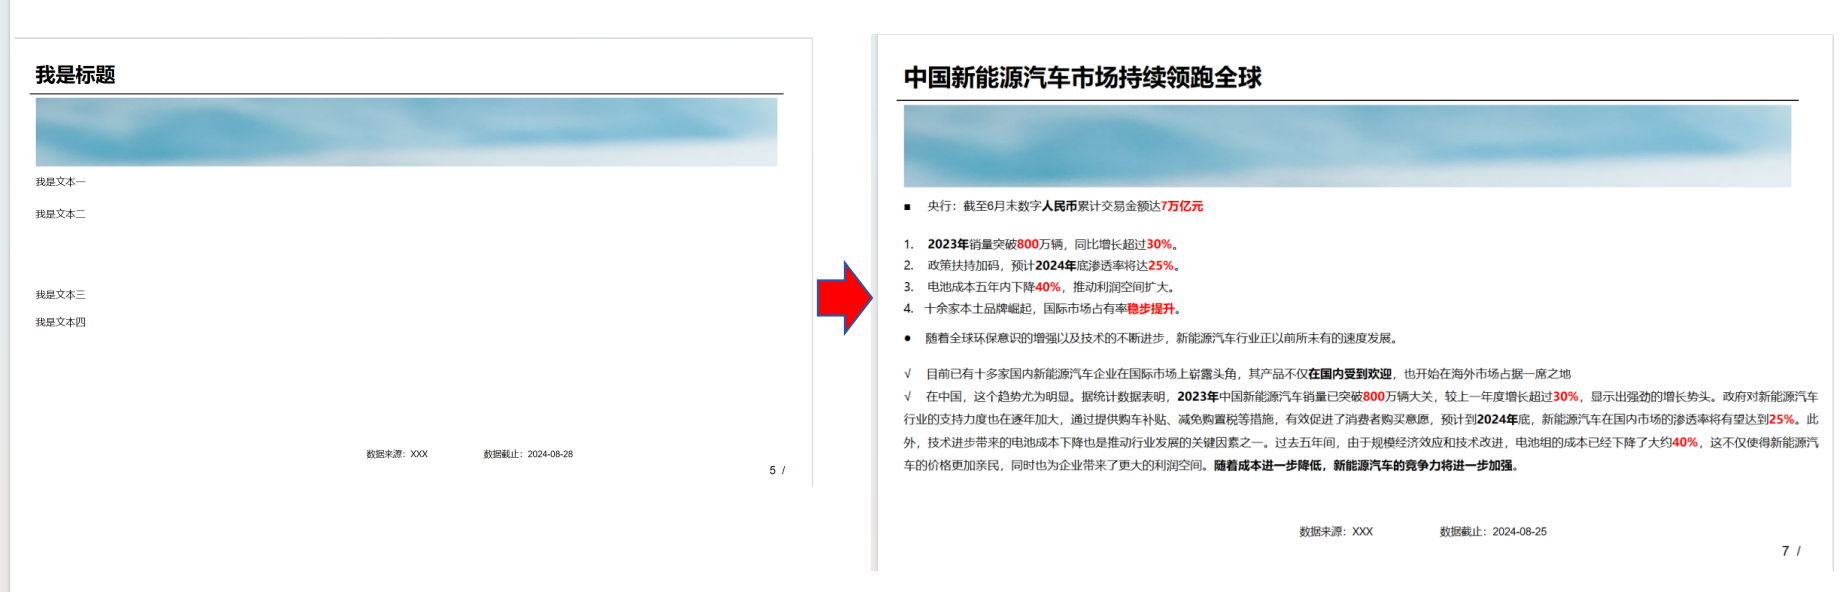
也就是最终想要根据左边的模板生成右边的样式
思路:
先获取PPT中的文本框索引和对应的文本,打印出来之后,再根据文本对应索引,去修改。
代码:
from pptx import Presentation
from pptx.util import Inches
from pptx.dml.color import RGBColor
from pptx_ea_font import set_font

def get_shape_center(shape):
    """计算形状的中心点坐标"""
    left = shape.left
    top = shape.top
    width = shape.width
    height = shape.height
    center_x = left + (width / 2)
    center_y = top + (height / 2)
    return center_x , center_y

def sort_shapes(shapes):
    """根据形状的中心点从上到下、从左到右排序形状"""
    return sorted(shapes, key=lambda shape: (get_shape_center(shape)[1], get_shape_center(shape)[0]))

def modify_shape_text(presentation_path,output_path, index_to_modify, new_text, Keyword_style_dict):
    # 加载PPTX文件
    prs = Presentation(presentation_path)

    # 获取第一张幻灯片
    slide = prs.slides[0]

    # 对形状进行排序
    shapes_sorted = sort_shapes(slide.shapes)

    # 遍历已排序的形状
    for idx, shape in enumerate(shapes_sorted):
        if shape.has_text_frame:
            if idx == index_to_modify:
                # 如果索引匹配,则替换文本
                # 保留原有的段落格式
                first_paragraph = shape.text_frame.paragraphs[0]

                # 从第一个段落运行复制格式
                original_run = first_paragraph.runs[0]

                # 清除原有的文本
                first_paragraph.clear()

                def modify_font_style(word,isFontColorRed,isBold):
                    run = first_paragraph.add_run()
                    run.text = word
                    if isBold:
                        run.font.bold = True
                    else:
                        run.font.bold = False
                    run.font.italic = original_run.font.italic
                    run.font.underline = original_run.font.underline
                    run.font.size = original_run.font.size
                    if isFontColorRed:
                        run.font.color.rgb = RGBColor(255, 0, 0)  # 设置颜色为红色
                    else:
                        run.font.color.rgb = RGBColor(0, 0, 0)  # 设置颜色为黑色
                    # 设置英文或数字的字体
                    run.font.name = original_run.font.name
                    # 设置中文字体
                    set_font(run, original_run.font.name)

                def keep_original_style(word):
                    run = first_paragraph.add_run()
                    run.text = word
                    run.font.bold = original_run.font.bold
                    run.font.italic = original_run.font.italic
                    run.font.underline = original_run.font.underline
                    run.font.size = original_run.font.size
                    run.font.color.rgb = RGBColor(0, 0, 0)  # 设置颜色为黑色
                    # 设置英文或数字的字体
                    run.font.name = original_run.font.name
                    # 设置中文字体
                    set_font(run, original_run.font.name)

                def to_highlight(word,style_dict):
                    if len(style_dict)!=0:
                        modify_font_style(word,style_dict["isFontColorRed"],style_dict["isBold"])
                    else:
                        keep_original_style(word)

                # 处理每一个词
                current_word = ''
                i = 0
                highlighted_parts = []
                normal_parts = []
                if len(Keyword_style_dict) !=0:
                    while i < len(new_text):
                        found_highlight = False
                        for word in Keyword_style_dict.keys():
                            if new_text[i:].startswith(word):
                                # 如果词在高亮列表中,则记录下来
                                if current_word:  # 如果当前有普通文本,先记录
                                    keep_original_style(current_word)
                                    normal_parts.append(current_word)
                                    current_word = ''
                                to_highlight(word,Keyword_style_dict[word])
                                highlighted_parts.append(word)
                                i += len(word)
                                found_highlight = True
                                break
                        if not found_highlight:
                            if i == len(new_text) - 1:  # 如果是最后一个字符,则记录下来
                                if current_word:
                                    keep_original_style(current_word+new_text[i])
                                    normal_parts.append(current_word+new_text[i])
                                break
                            else:
                                current_word += new_text[i]
                                i += 1
                else:
                    normal_parts =[new_text]
                    keep_original_style(new_text)

            text_frame = shape.text_frame
            print(f"Shape Index: {idx}, Type: Text Box")
            paragraph_texts = '\n'.join([paragraph.text for paragraph in text_frame.paragraphs])
            print(paragraph_texts)
            print("---")  # 分隔每个文本框的内容
        else:
            print("Not a Text Box")

    # 保存修改后的PPTX文件
    prs.save(output_path)

# 替换为您的PPTX文件路径
presentation_path = 'D:\\desktop\\111.pptx'
# 替换为您的输出文件路径
output_path = 'D:\\desktop\\111.pptx'
# 假设你需要修改索引为X的文本框的内容
index_to_modify = 6
new_text = "央行:截至6月末数字人民币累计交易金额达7万亿元"
Keyword_style_dict={"人民币":{"isFontColorRed":False,"isBold":True},"7万亿元":{"isFontColorRed":True,"isBold":True}}

modify_shape_text(presentation_path,output_path, index_to_modify, new_text, Keyword_style_dict)
然后问题来了,怎么知道目标文本框对应的索引值是多少呢?
答:可以先将index_to_modify设置为0,运行一下这个程序,会打印出来每个文本框的内容以及对应的索引值。然后就知道了索引值是多少,修改后再运行一遍程序就好了。
收藏全部评论(1)
最新
发布评论
评论